↓ Skip to main content

Anger Is a Tactic: How to Deal With People Who Use Aggression to Get Their Way

You know the person. The meeting gets tense, their voice rises, maybe a fist lands on the table, and within a minute the room gives in and they get their way. Later someone whispers “that’s just how they are” and the decision stands.

I never believed that framing. Temper at work is rarely just an emotional storm, it is a negotiation move, and the research on it is unusually clear: it extracts concessions from people who cannot walk away, it destroys value everywhere else, and it collapses the moment the target stops playing. Once you see it as a tactic, dealing with it stops being therapy and becomes strategy.

The Outburst Is Making an Argument
#

Start with the finding that explains why the behavior persists: anger works, in the short term, on the people it is aimed at.

In a series of classic experiments, negotiators who were told their opponent was angry conceded more than negotiators who were told the opponent was happy (Van Kleef, De Dreu & Manstead, 2004). The interesting part is the mechanism. The targets were not scared into submission; they did the math. They read the anger as information about the opponent’s limit, concluded the opponent would not move, and adjusted their demands to avoid impasse. Related experiments found that angry negotiators win larger concessions from their counterparts (Sinaceur & Tiedens, 2006).

The mechanism is a single inference on the target’s side, and the inference carries its own break condition:

An angry outburst leads the target to infer no movement; if the target cannot walk away the target concedes and the tactic pays, and if the target has power the target retaliates and the tactic backfires

Anger also buys status. Across four studies, people who expressed anger were judged more competent than people who expressed sadness, and observers conferred higher status and even higher salary offers on them (Tiedens, 2001). We read anger as confidence, and we promote what reads as confidence.

So the person yelling in the meeting is running a computation that has paid out for years: volume signals a hard limit, the limit signals competence, and everyone else absorbs the cost of avoiding the fight. Expecting them to stop out of politeness is expecting them to abandon a winning move.

Where the Tactic Stops Working
#

The same literature that shows anger working also shows precisely where it fails, and the boundary matters more than the effect.

First, the signal only works while the behavior is consistent with it. In the 2004 experiments, when the “angry” opponent started making large concessions, the effect vanished; targets stopped trusting the display and went back to their own numbers (Van Kleef et al., 2004). Anger is an argument about a limit, and any behavior that contradicts the argument wins.

Second, the tactic depends on who is receiving the anger. When researchers pitted anger against power, low-power participants conceded to an angry adversary regardless of whether the anger was appropriate, but high-power participants confronted with inappropriate anger retaliated and demanded more, not less (Van Kleef & Côté, 2007). Anger extracts value downward and invites punishment sideways or upward.

Third, field data from hundreds of real online dispute mediations found that anger expression lowered resolution rates overall, in significant part because it triggered angry responses from the other party; only when the counterpart was especially vulnerable did the anger fail to hurt the expresser’s outcome (Friedman et al., 2004). In relationships that continue past the transaction, anger mostly burns the expresser.

And the flow is almost entirely one-directional. Sutton summarizes the frequency data in The No Asshole Rule: perceived nastiness is estimated to run downward (boss to subordinate) in 50 to 80 percent of workplace occurrences, versus roughly 1 percent upward. Interview studies of workplace anger episodes found the same asymmetry from the other side: subordinates were the least likely to confront the target of their anger and the most likely to consider the incident unresolved (Fitness, 2000).

Aggression survives on a power gradient and on the target’s silence, which is why the people who use it are so often leaders and so rarely peers.

The Hidden Cost
#

The defense of these people is always the same: they get results. The research says those results carry costs nobody tracks.

The founding study of abusive supervision followed 712 employees and found that those who perceived their supervisor as abusive were more likely to quit, and the ones who stayed showed lower job and life satisfaction, lower commitment, and depressed perceptions of justice (Tepper, 2000). Fifteen-plus years of follow-up research, synthesized in Tepper’s Annual Review, established the pattern as one of the most robust in organizational psychology. The abuse also cascades: managers mistreated by their own bosses go on to mistreat their subordinates (Mawritz et al., 2012).

If you think that is soft-outcome stuff, the hard-outcome studies are worse. Researchers randomized 24 neonatal intensive care teams to either neutral comments or a few mildly rude remarks from a visiting “expert,” rudeness deliberately unrelated to the team’s actual performance. The rudeness-only teams’ diagnostic and procedural performance dropped significantly (2.6 vs 3.2 and 2.8 vs 3.3 on the judged scales), with rudeness alone explaining nearly 12 percent of performance variance. The cause was social: the teams stopped sharing information and asking each other for help (Riskin et al., 2015). A few sentences of mild rudeness measurably degraded how well expert teams saved babies, and the mediators were exactly the collaborative behaviors an angry leader suppresses.

Then the rudeness spreads. Witnessing rudeness makes people more likely to judge ambiguous behavior as rude and to behave rudely themselves (Foulk, Woolum & Erez, 2016). Witnesses of bullying report increased stress and fear of becoming targets (Sutton). Prevalence data suggests nearly everyone experiences incivility: across 14 years of polling, 98 percent of workers reported uncivil behavior, and by 2011 half reported being treated rudely at least weekly, up from a quarter in 1998 (Porath & Pearson, HBR).

The aggressor’s visible win is real, but it is paid for by silent losses in everyone else’s judgment, information flow, and retention.

Why They Do It
#

Two findings changed how I read these people.

The first is causal: power plus felt incompetence produces aggression. Across studies, people with power who doubted their own competence were the most aggressive toward subordinates, and competent subordinates were the preferred targets of their put-downs (Fast & Chen, 2009). The boss who lashes out at the strongest engineer in the room is often running from exactly that engineer’s competence.

The second is Sutton’s distinction between the temporary and the certified asshole: someone having a bad day versus someone “persistently nasty” who leaves targets oppressed and humiliated and aims at people less powerful (The No Asshole Rule). The distinction matters because the responses differ. A bad day deserves grace; a pattern is a system that will keep harvesting concessions until someone changes the price.

Read aggression as information: it tells you the person’s other tools are insufficient for the situation, which is exactly why the tactic concentrates at the top, where it is tolerated, and among the insecure, where it is needed.

The Playbook
#

The research maps to a small number of concrete moves.

1. Separate the claim from the volume. The outburst is an argument that a limit has been reached. Answer the argument, not the volume: ask what specifically is unacceptable, what they need, and what would change their position. Asking those questions works because the mechanism is inference; when you engage the substance and your own behavior contradicts the “hard limit” reading, the display loses its informational value (Van Kleef et al., 2004).

2. Do not reciprocate. The field evidence is unambiguous that reciprocated anger is what destroys outcomes (Friedman et al., 2004). Matching their tone converts a solvable disagreement into a status fight, and status fights involving a leader have exactly one winner available. Stay slow, stay concrete, and let the asymmetry between your tone and theirs become visible to the room.

3. Name the behavior once it crosses the line. The dual threshold model of anger in organizations distinguishes an expression threshold (communicate rather than suppress) from an impropriety threshold (display that violates norms and starts doing damage) (Geddes & Callister, 2007). Functional anger sits between the thresholds; the table-pounder lives beyond the second one. Naming it does not have to be dramatic: “I want to solve this, and I need you to lower your voice so we can” is a boundary, not an attack. The key is to do it early, because subordinates who swallow anger consistently rate their incidents unresolved, and unresolved incidents compound (Fitness, 2000).

4. Attack the dependency, not the person. Anger extracts concessions from those who cannot walk away and invites retaliation from those who can (Van Kleef & Côté, 2007; Friedman et al., 2004). The practical translation is simple: build alternatives. Document your contributions where others see them, cultivate sponsors outside your reporting line, keep your skills portable, keep your savings real. You do not need to quit to be less dependent; you need the aggressor’s threat model about you to weaken. Half the power of the tactic evaporates the day they are no longer sure you would stay.

5. Contain the contagion. If you manage anyone exposed to the aggressor, protect their collaborative behavior deliberately. Debrief the incident, keep information flowing, and make help-seeking explicitly safe, because those are the two channels rudeness shuts down first (Riskin et al., 2015; Foulk et al., 2016). Teams absorb an aggressor’s mood by default (Sy, Côté & Saavedra, 2005); somebody has to interrupt the absorption.

6. If you have organizational power, make it a firing matter. The strongest evidence-based organizational response is also the bluntest: refuse the trade. Netflix’s culture memo says it in one line: “No matter how brilliant someone may be, there’s no place in our Dream Team for people who don’t treat their colleagues with decency and respect” (Netflix culture memo). Sutton’s cost arithmetic (he calls it Total Cost of Assholes: HR hours, turnover, witnesses’ lost productivity, legal exposure; one executive’s estimate for a single engineer ran to about $160,000 a year) exists so leaders stop pricing these employees by output alone (The No Asshole Rule). And the ground must be safe before anyone will name the problem: Google’s Project Aristotle found psychological safety the most important of the five dynamics separating its effective teams from the rest (Duhigg, “What Google Learned From Its Quest to Build the Perfect Team”). Psychological safety is precisely what a chronic aggressor destroys.

What to Do Next
#

Pick the next encounter and prepare one sentence for it. Something like “I will engage with the problem when we can discuss it calmly,” said once, neutrally, and then silence.

Inventory your dependency while calm: who else knows your work, how portable are your skills, how many months of runway do you have. The inventory is not defeatism; it converts you from a low-power target, the only kind this tactic works on, into a high-power one.

Write down the incidents, dates included. Patterns need data, and data is what turns “I feel uncomfortable” into a case a leader or HR can act on.

And if you have power over one of these people, stop asking whether they are worth the trouble and start computing what they cost; the research says the invoice is much larger than their manager has ever seen.

See also
#

References
#


Getting Noticed in the LLM Flood: Compete on What Cannot Be Generated

For most of the internet’s life, the rule was simple: make something good, put it somewhere findable, and the channels would carry the rest. That rule assumed a scarcity that no longer holds. When a model can draft a competent essay, tutorial, landing page, or thread in seconds, the supply of “good enough” writing goes effectively infinite, and good stops being the thing that gets you noticed. The scarce thing has moved upstream, from content to the trust that lets any single reader pick your work out of the flood.

The Flood Has Two Sides
#

A flood that is impossible to read is also a flood that is impossible to be read in. These are the same problem seen from opposite ends.

The reader’s version is a filtering problem: too much coming at you, too little time to sort it (see Keeping Up With AI Is a Losing Strategy). The maker’s version is a discovery problem: your work is one drop in a self-replenishing ocean, and the ocean refills faster than anyone can drink.

The root cause is identical. As Herbert Simon put it half a century before LLMs, “a wealth of information creates a poverty of attention.” What changed is that the wealth of information stopped requiring people to produce it, so the supply curve bent from steep to vertical. Attention did not scale with it. That leaves every creator competing for a fixed resource against a supply that has no ceiling.

“Good” Is Now the Floor
#

It used to mean something to publish clear, well-structured, useful writing, because producing it took time, skill, and effort, and that effort was itself a signal. When the median post can be generated in seconds and is, on the surface, as clean as anything a careful human would ship, clarity and structure stop signaling much. They become the default, the minimum readers expect and immediately forget.

This is Sturgeon’s law (“ninety percent of everything is crud”) with the dial turned up: not only is most content mediocre, but the mediocre is now polished enough to pass for good, which forces readers to assume everything is mediocre until proven otherwise. The practical effect is that competence no longer earns attention; it merely avoids an immediate bounce. You cannot out-write the flood, because the flood is now competently written.

Compete on What Cannot Be Generated
#

If the surface layer is commoditized, the advantage moves to the layers a model cannot generate, and almost all of them are slow, specific, and human. Kevin Kelly named these the “generatives” in Better Than Free: the qualities that stay valuable precisely because copies are free. His list, written in 2008 about an earlier wave of abundance, maps almost perfectly onto the problem of being noticed now. Four of them do most of the work.

Authenticity is the sense that a real, specific person made this for a reason they will stand behind. A model can imitate a voice, and even the surface texture of the life behind it: a recorded mistake, a hard-won opinion, a detail only someone who was there would notice. What it cannot provide is the underlying record that makes those details checkable, which is why authenticity has to be backed by proof rather than merely asserted (see Proof of Work, below).

Embodiment is the version of the work that lives in the physical, social world: a live talk, a conversation, a workshop, a thing you can point to in a room. It cannot be copied at all because it is not made of text, and it is where the strongest trust gets built.

Personalization is work tuned to a specific reader or community rather than aimed at everyone. The flood is generic by construction; anything that clearly was not, anything that names a particular reader’s problem in a particular context, stands out against it by contrast alone.

Findability is the quality most creators neglect, and the focus of this whole article. As Kelly wrote, “when there are millions of free things requesting our attention, being found is valuable.” In a flood, distribution is not the layer you add after the work is good; it is the work.

Proof of Work Is the Signal That Survives
#

If readers now assume competence is fake by default, the only thing that reliably breaks through is evidence that a real person actually did the thing behind the writing. Call it proof of work, borrowing a term from systems where trust is established by demonstrating costly effort rather than by asserting it (proof of work).

The tempting version of this claim is that the right story reads as authentic and therefore cannot be faked. That claim fails once models can fabricate the same story. A fabricated postmortem with specific-sounding numbers, a plausible failure chain, and the right tonal markers passes most readers’ filters, because few will check whether the project existed, whether the numbers are real, or whether the author lived it. The cost asymmetry the argument depends on, expensive to produce but cheap to verify, inverts: the story is now nearly free to generate, verification still costs real effort, and readers rarely pay it.

What cannot be faked at scale is not the story but the record it claims to sit on. A real project leaves a wide trail, commits, issues, deployed systems, other people who remember it, a history you can point to. The postmortem itself is cheap to hallucinate; the artifacts it references are not. The durable signal is not “does this read like lived experience” but “can I trace it to something independent of the author’s word,” and that is a harder bar than most writing clears.

The verification chain a claim has to survive looks like this.

Funnel: claims with a verification surface trace to commit history, incident reports, or people who remember the work and earn trust, while claims with nothing to check are assumed generated and skipped

That bar is why the familiar examples carry weight only when they are traceable. A postmortem of a project that failed, with real numbers and real reasons, matters if you can link the project, the commit that introduced the bug, the incident report. An experiment you actually ran, with setup and outcome, matters if the setup is reproducible and the data is there. A thing you built and genuinely use matters if the repository exists, has a history, and other people can run it. Strip the traceability and the same sentences are indistinguishable from hallucination. Proof of work is not a quality you can write into a paragraph; it is a verification surface you either leave behind or do not, and the cost that makes it trustworthy is paid in building that record, not in describing it.

Proof of work is the producer’s version of the moat argument elsewhere on this blog: when the easy-to-copy layer is free, the advantage relocates to the layers that compound through time and cannot be cloned (see Feature Parity Is Not a Moat). For a creator, those layers are a track record, a body of specific work, and the relationships built around it.

Be a Source, Not an Echo
#

Most generated content restates things other people already said, which means most of the flood is echo. The way to stop being part of the flood is to be the thing it is restating.

A source is someone who produces a fact, an observation, a measurement, an argument, or a story that did not exist in that form before they wrote it. An echo is everyone, human or machine, who restates it. The flood is almost entirely echo, which means even a small amount of genuine source material stands out clearly against it.

The lever is to bias every piece toward the thing only you could have written: the result you observed, the mistake you made, the opinion you hold and can defend, the specific reader you are addressing. Narrow beats broad here, because narrow is where specificity lives and specificity is what an echo cannot manufacture. A durable body of narrow work also compounds: ten pieces on the same corner of a problem make you the address for that problem, where ten unrelated pieces make you another drop.

Relationships Are the Distribution Layer That Does Not Saturate
#

Every algorithmic channel is now full, and getting fuller, and the curve points one way. The one channel that does not saturate the same way is direct human relationship, the small set of people who know you, trust your work, and pass it on because they want to.

These are not “followers” in the metric sense; they are the thin layer of real acquaintance, parasocial or otherwise, that turns “I made a thing” into “someone I trust made a thing.” Trust is the only distribution medium that the flood dilutes more slowly than it dilutes everything else, because trust cannot be manufactured by a model either. This is why the unglamorous work of replying, citing, collaborating, and showing up over years outperforms any broadcast tactic in a saturated feed. It is also the version of distribution that compounds, while a clever hook compounds for about a day.

The Bottleneck Moved to Trust
#

The uncomfortable reading of all this is that “make good things” was never the whole strategy; it was a strategy that worked while good things were scarce. They are not scarce anymore, and they will not be again.

What is scarce, and getting scarcer, is the trust that lets a reader choose one piece out of a million. Trust is built only from the inputs a model cannot generate: your time, your experience, your track record, and your relationships. Getting noticed in the flood is not a louder version of the old playbook; it is the decision to stop competing on the layer that went free, and to put everything onto the layers that never will.

What to Do Next
#

Stop optimizing for volume. Posting more into an infinite stream makes you more of the stream, not more visible inside it, and the marginal post now competes with machines that post faster, for free.

Bias every piece toward proof of work. If a reader cannot tell whether a real person did the thing behind the writing, they will assume not, so leave a verification surface they can actually check: link the repository, the data, the incident report, the commit, so the claim rests on something independent of your word rather than on how lived the prose sounds.

Write what only you can write, and narrow until that is true. Specificity is the cheapest signal that survives generation, and a narrow, durable body of work is what makes you the address for a problem instead of a drop in the flood.

Treat distribution as the work, not the afterthought. Findability is a generative in its own right, and in a flood it is the generative that decides whether any of the rest gets read.

Build the channels that do not saturate. A small set of real relationships, maintained over years, will carry your work further than any algorithmic tactic, and it is the one distribution layer a model cannot generate.

See also
#

References
#

  • Attention economy (Wikipedia) - Simon’s “a wealth of information creates a poverty of attention,” the root framing for why a content flood is a trust problem
  • Kevin Kelly, “Better Than Free” - the “generatives” that stay valuable when copies are free, including authenticity, embodiment, personalization, and findability
  • Sturgeon’s law (Wikipedia) - “ninety percent of everything is crud,” sharpened here by the fact that the crud is now polished enough to pass for good
  • Information overload (Wikipedia) - the long-standing name for the reader’s condition this article takes as its starting point
  • Proof of work (Wikipedia) - trust established by demonstrating costly effort rather than by assertion, the property that lets real work stand out against generated content
  • Parasocial interaction (Wikipedia) - the one-to-many relationship layer that distributes work without saturating the way algorithmic feeds do

Teach Your Agent Skills to Use Tools That Render

The cheapest upgrade I have made to an agent skill was not a better prompt or a bigger model. It was teaching the skill to emit a mermaid diagram instead of a paragraph. Once the skill could draw, I could check its work by looking instead of reading, and looking is the one verification that stays fast when the prose has buried you.

The highest-leverage thing you can do to an agent skill is wire it to a small tool that renders, because a rendered artifact moves verification from reading to looking, and looking is cheap, fast, and hard to fool.

Why prose-only skills plateau
#

A skill that only writes prose hands you prose to verify. Prose asks you to read, and reading is exactly the bottleneck that working with agents moved into the foreground: the scarce, serial, finite attention you have left once generation became free (Attention Engineering).

The trap is that prose feels productive to generate and expensive to check. The agent writes a fluent paragraph describing the data flow, the spec, or the migration plan, and you skim it and approve it, because reading it carefully would cost more attention than you have. A skill that outputs only text is a skill that can only be checked by the slowest checker you own, and the one that tires first, which is you, reading.

The pattern: pair the skill with a tool that renders
#

The fix is to give the skill a tool that turns text into something you can inspect at a glance. The tool does the deterministic part, the layout, the rendering, the syntax checking, and the skill does the generative part, deciding what to put in the diagram. The concerns separate cleanly, and the output becomes inspectable in a way prose never is.

The split of labor looks like this:

flowchart LR
    S[Skill, the generative half] --> T[Text source, mermaid or DBML]
    T --> R[Renderer, the deterministic half]
    R --> A[Inspectable artifact]
    A --> H[You, the fast checker]
    T --> G[Git, so changes are reviewable]

Pairing a skill with a renderer is the same move as Verifying Code Without Reading It, applied to the artifacts a skill produces: stop trying to read, start trying to verify, and pick for each artifact the cheapest checker that catches the failure you care about. For a lot of artifacts, the cheapest checker is a picture.

Mermaid in the SDLC process
#

I started adding mermaid diagrams to my SDLC skills, and the payoff was immediate. A plan that used to be three paragraphs of “first we do this, then that, and this component talks to that one” now ships with a sequence diagram. A spec now ships with a state diagram or a flowchart of the happy path.

The diagrams fail in ways prose hides. A sequence diagram with a message that has no receiver makes a missing step obvious. A flowchart with two boxes that both claim to write the same column makes a race condition visible before a line of code exists. The wrong diagram is obvious in two seconds; the wrong paragraph is buried in the fourth reading, if it ever surfaces.

Mermaid is the right tool for a skill for three reasons. It is text, so the agent generates it directly, the same way it generates any other output. It renders natively where the work already lives, because GitHub renders ```mermaid blocks in Markdown and most static site generators do too. And it diffs cleanly, because the source is text, so a change to the plan shows up in the pull request as a diff you can review instead of a picture you have to compare by eye.

Text-based tools are the best fit for skills
#

The mermaid case generalizes into a rule I now follow. When you pick a tool for a skill to drive, prefer a text-based one, because text is the medium the agent speaks, the medium git tracks, and the medium that renders to the artifact you inspect.

DBML is the database-schema version of the same idea. It is a small markup language for tables, columns, and foreign keys, and a few lines of it render to a full entity-relationship diagram on dbdiagram.io. A skill that describes a schema now emits DBML, and I see the structure of the data model, the missing relationship, the redundant table, before I have read a single column definition.

The text basis is what makes it fit an agent workflow. The agent writes DBML the way it writes code, the file lives next to the migration that creates the tables, it reviews and diffs like code, and the rendered diagram is a view on top of it rather than a separate artifact that drifts. When the schema changes, the DBML changes in the same commit, and the diagram is never stale.

Where the visual tool fits: on the human side
#

Preferring text-based tools does not mean GUI tools have no place. drawdb is the mirror image of DBML: a browser editor where you drag tables and draw relationships by hand, and it exports the SQL for whatever you sketched.

The division of labor that works for me is to let the agent drive the text-based tools and let myself drive the visual ones. I sketch in drawdb when I am still figuring the model out, when I want to move boxes around and feel my way through the design, and then the SQL/DBML it exports becomes an input the agent works from. I let the agent drive DBML when the schema is already decided and I want a rendered view of it inside the repository. Text-based tools go in the skill, where the agent is fast and generation is cheap; visual tools go in my hands, where exploration is slow and taste is required.

How to pick the next tool to wire in
#

Three tests decide whether a tool is worth wiring into a skill.

The tool must be text-based, or have a text representation the agent can produce. The whole pattern breaks if the agent cannot generate the source the renderer consumes.

The tool must render to something inspectable, a diagram, a table, a diff, a graph. If the output is still prose, you have added a dependency and gained no new kind of check.

And the tool must be narrow enough that the skill can use it reliably. Mermaid and DBML win here because they are small languages with a fixed grammar, not sprawling APIs the model has to guess at. A tool the model gets wrong half the time is worse than prose, because you spend your attention debugging the tool instead of the idea.

What to Do Next
#

Pick one skill you already run that emits prose and teach it to render. If it describes a flow, teach it mermaid. If it describes data, teach it DBML. If it describes a sequence of messages between components, teach it a sequence diagram.

Then read the next output it produces as a picture instead of a paragraph, and notice where your eye catches in two seconds what your reading would have missed in twenty minutes. That gap, between the cost of looking and the cost of reading, is the whole reason to give your skills tools that render.

See also
#

References
#

  • Mermaid - text-based diagramming that renders in GitHub and most docs, the tool I wired into the SDLC skills
  • DBML syntax - a markup language for database schemas that renders to entity-relationship diagrams
  • dbdiagram.io - the renderer for DBML, where the text turns into a diagram
  • drawdb - a browser-based visual ER editor for sketching schemas by hand and exporting SQL

What the Author Brings When the Model Writes

Producing sentences was never the part that made writing worth reading. When a model can produce clean, well-structured prose about anything in seconds, the value of an author stops being the prose and comes down to the one thing the model cannot supply: a reason the words should exist at all.

Writing Was Always Two Jobs
#

For as long as writing was hard, two very different jobs were fused inside it. One was mechanical: choosing words, ordering sentences, hitting the register a reader expects. The other was everything that made the writing worth a stranger’s time: deciding what was true, which detail mattered, what to assert and what to leave out, what claim I would stand behind if someone pushed back.

The two jobs looked like one task because the same person did both, and because the judgment was invisible unless the prose was done well. LLMs did not replace the author; they split the author in two and automated only the half that was always the easier one to learn.

The split looks like this:

Stacked bar splitting writing into the mechanical half that the model automates and the judgment half that stays with the author as the entire product

The Model Is Fluent and Has Nothing to Say
#

A model trained on the corpus of everything humans have written can generate plausible text on any subject, and that fluency looks like understanding from the outside. It is closer to a lossy compression of everything already said, as Ted Chiang argued in calling ChatGPT a “blurry JPEG of the web”.

The model can only recombine what exists; it has nothing of its own to add. It has not run the experiment, taken the risk, held the opinion, or been wrong in public and had to fix it. Fluency without experience produces prose that could have been written by anyone, which is exactly the prose the internet now has too much of.

What the Author Brings That the Model Cannot
#

Four things do most of the work, and each is scarce for the same reason: it is paid for in something other than typing.

Something to say. A real piece of writing starts from an observation, a result, a mistake, or a conviction that did not exist in the corpus in that form. The author has lived something the model has not. The trace of that experience, a number that was actually measured, a failure that actually happened, a stance the author will defend, is the only material the model cannot manufacture.

Judgment about what is true. The model will produce a confident answer either way, which is why its confidence is worth almost nothing as a signal. An author commits: this is right, this matters, this is the claim I am making. That willingness to be wrong, narrowing a general cloud of plausibility down to one assertion a reader can check or reject, is the act the model cannot perform, because the model has no stake in being correct.

Stakes and accountability. Writing with a name on it can be wrong, criticized, quoted against its author, and remembered. That risk is precisely what gives the words weight to a reader, who is deciding whether to trust a person, not a process. A model has nothing to lose from a false sentence: the sentence costs it nothing, costs an author something, and readers sense that asymmetry even when they cannot name it.

The thinking that writing forces. Writing is not the transcription of finished thought; for most authors, myself included, it is how the thought gets finished at all. Offload the whole job and I keep the artifact but lose the part that changed me, the slow, uncomfortable work of discovering what I actually believe by being forced to say it precisely.

The Trap of Offloading the Wrong Half
#

Prose generation is so cheap and so good that I am tempted to also let the model decide what to say, and then edit a draft into something shippable. Let the model choose the claim on every piece and the work becomes indistinguishable from the flood, because the work is the flood, recompressed from the same corpus by a slightly different prompt.

The moment you let the model choose the claim, you have stopped being the author and started being the first reader of the model’s writing. That arrangement produces a thinner kind of work, the kind that does not earn the trust that makes anyone return.

The useful line is not “human-written” versus “AI-written,” and never was (see Written by for how this blog labels AI involvement). The useful line is whether a human mind made the decisions that determine whether the piece is worth reading: what to assert, what to omit, what experience anchors it, and whether the claim is one the author will stand behind.

What to Do Next
#

Decide what the piece is for and what claim it is making before the model writes a single sentence, because that decision is the work and the prose is downstream of it.

Anchor every piece in something the corpus does not contain. A measurement you took, a failure you caused, an opinion you hold and can defend, a reader you are specifically addressing, is the only material that keeps the writing from being echo.

Put your name behind it and mean it. The accountability is not a cost you pay for publishing; it is the source of the weight the writing carries. A reader can feel its presence or absence in the first paragraph.

The prose is now the cheapest output. The judgment behind it is the entire product.

See also
#

  • Getting Noticed in the LLM Flood - the producer’s mirror of this piece: once the writing is good enough to be the floor, attention moves to trust and distribution
  • The Shifting Bottleneck - the pattern of the constraint moving one level up when a lower one is automated, here from prose production to judgment
  • The Acceptance Gap - the parallel problem in code: the model produces, deciding it is acceptable is the human part that stays
  • Written by - this blog’s disclosure policy, which exists because the author-versus-echo distinction matters
  • Keeping Up With AI Is a Losing Strategy - the reader’s side: why more fluent content is the wrong thing to optimize for

References
#


Attention Engineering: Your Attention Is the Bottleneck

Generation stopped being the expensive part of working with LLMs. You describe, the model produces, and a plausible answer arrives in seconds. The expensive part is now your attention, and almost nobody has updated how they spend it.

We kept the habits from when writing the code was the hard part. We hover over the agent while it works, we read every diff it produces, we re-check by hand what a check could check for us, and we call the exhaustion that follows “using AI well.” It is not. It is attention spent on the half of the problem that is already solved, while the half that still needs a human mind gets the leftovers.

Attention engineering is the deliberate practice of treating your own attention as the scarce resource, and allocating it to the parts of an agent workflow where a mind is actually required.

Attention Is Not Time
#

The first mistake is to confuse attention with time. Time expands to fit the work; attention does not. You can run eight agent sessions in parallel in the same number of hours, but you cannot read, judge, and decide on eight outputs in parallel. The part that parallelizes is generation, which is the part that no longer needs you. The part that needs you, deciding what is good enough, is strictly serial and strictly finite.

This is why spawning more sessions often makes you slower, not faster. Each open session is a claim on working memory, and working memory is small and slow to refill after a switch. The literature on cognitive load has been clear about this for decades: heavy switching fragments attention and produces shallow processing, and the cost is paid by the task you switched into, not the one you left. Parallel agents widen the generation pipe and narrow the decision pipe at the same time, and the decision pipe is the one that matters.

Where Attention Leaks
#

Most of the fatigue people blame on AI is really misallocated attention. It leaks in four predictable places.

Watching the agent generate. The stream of tokens is mesmerizing and almost useless. You cannot usefully steer a model at token speed, and the sense of “supervising” it is a feeling of productivity, not productivity itself. You are attending to a process you cannot improve by attending to it.

Re-verifying what a check could verify. The model says the bug is fixed, and instead of trusting a test, you re-read the diff looking for the fix with your own eyes. This is the acceptance gap run backwards: you spend scarce, taste-grade attention on correctness, the one thing that can be encoded and handed off. A minute of writing the check would have saved an hour of reading, forever.

Context-switching between sessions mid-judgment. You decide on session A until a notification pulls you to session B, and back. Each switch leaves a residue of the previous task in your head, and the decision you return to is made with half your mind still elsewhere. The work feels continuous and is actually being done in shallow fragments.

Signing off without attending. The pull request opens, CI is green, the description looks right, and a feeling forms before the code is read. We have known for a long time that most review works this way, and the arrival of machines writing the diff has not made the reading more rigorous, only the ritual more exhausting. And attention collapses fastest on the work you had no investment in to begin with: it defends itself on what you care about and quietly gives up on what you do not (The Cost of Work You Did Not Choose).

The Leverage Ranking
#

Not every part of an agent workflow needs your attention equally, and the error is treating them the same. Rank them by how much they need a human mind.

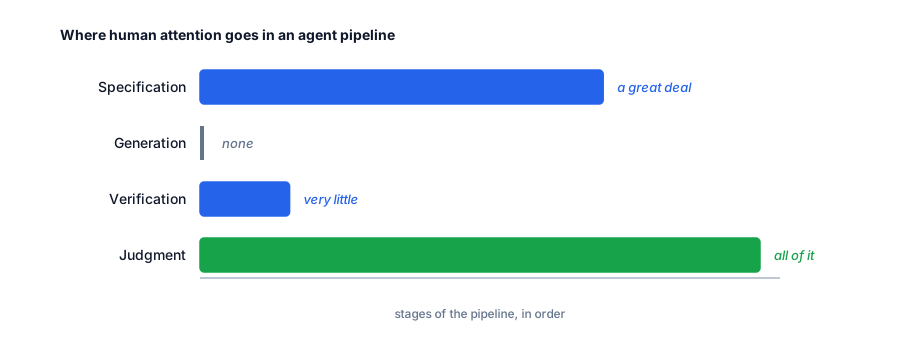
Here is the workflow as a pipeline with the attention budget laid over it:

Bar chart of human attention per pipeline stage: specification takes a great deal, generation none, verification very little, and judgment all of it

Generation needs none. Stop attending to it. Hand over a finished intent and walk away.

Verification, the question of whether it did the thing, needs very little, once you encode it as a check. A failing test that must pass is attention that pays itself forever, for free, whether or not you are watching. The residual cost is exactly the set of things you have not yet bothered to encode.

Specification, the question of what you actually want, needs a great deal, and it is upstream. Attention spent writing the spec pays a higher dividend than attention spent editing the output it produced, because a good spec prevents the wrong output from existing at all.

Judgment, the question of whether the result is the thing you wanted, needs all of it, and it cannot be delegated. This is the taste decision, the “good enough, ship it” moment, and it is the last compounding thing you do.

The skill is to starve the first two and feed the last two.

Attention Engineering, In Practice
#

A few rules hold up.

Spend attention upstream, not downstream. The hour you invest in the specification is worth ten hours of fixing the generated output, because the output is downstream of the spec and inherits all of its omissions. If you keep editing what the agent produced, the problem is usually the prompt you did not write, not the model.

Encode correctness until it costs you nothing. Every check you write is attention you never have to spend again. The goal is to shrink the “verify by hand” pile to the set of things that genuinely cannot be expressed as a check, which is smaller than most people think.

Parallelize generation, serialize judgment. Let many sessions run at once, but do all your deciding in one focused pass, one session at a time, with the others closed or paused. The model is the part that benefits from parallelism. Your judgment does not, and pretending otherwise is how you ship work you never actually read.

Refuse to supervise. If you find yourself watching the agent work, you have either failed to specify the task well enough to walk away, or you have not built the check that would let you trust the result without watching. Both are fixable, and fixing them is a better use of attention than the watching.

Protect the taste decision. It is small in duration and enormous in leverage, and it is the one thing no tool will ever do for you, which is exactly why it is worth protecting from the noise of everything else.

The Implication
#

The constraint has done what it always does when a layer gets automated: it moved up the chain, from generating the work to deciding whether it is good enough (The Shifting Bottleneck). What is new is that the new constraint is not another task you can delegate. It is your own attention.

The ceiling on what you produce with agents is not the model, not the tooling, and not how many sessions you can spawn at once. It is how much focused attention you can bring to the few decisions that require a mind, and how ruthlessly you keep that attention off the many that do not.

The people who get the most out of LLMs are not the ones with the cleverest prompts. They are the ones who learned to walk away from generation, to encode everything checkable, and to save their finite attention for the specification and the taste that only they can supply.

Working with agents is not a prompting skill. It is an attention skill, and the sooner you treat your attention as the bottleneck it has become, the more of it you will have for the work that is actually yours to do.

See also
#

References
#

  • Cognitive load - grounds why attention is finite: working memory is small, and heavy context switching fragments it into shallow processing

My Philosophy

If you read enough of what I have written, one sentence underlies all of it: encode your judgment into artifacts that outlive your attention. The artifacts change, the principle does not.

A blog post is such an artifact. A skill file is one. The principles file I keep is one. The form runs from the trivial to the sacred, and the same instinct produces all of them: I do not trust my attention to be present when it matters, so I put the judgment somewhere it can survive without me.

This is not a philosophy of throughput, though it can look like one. I am not trying to do more. I am trying to do things that keep mattering after I stop doing them. The victory condition I keep describing, in different vocabularies, is to make myself unnecessary at the layer I currently occupy, so I am free to go find the next one. That is what I am optimizing for, and once you see it, the rest follows.

The frame: the constraint always moves
#

My master mental model is the Theory of Constraints, and I reach for it more than any other. Every system has exactly one binding constraint at a time, and improving anything other than that constraint is wasted effort. The moment you relieve the constraint, it relocates: it does not disappear, it just moves. Automate code production and verification becomes the bottleneck; solve verification and feature selection becomes the bottleneck; solve feature selection and the question of what deserves to exist at all becomes the bottleneck.

The chain I keep chasing looks like this, and it never terminates:

Staircase of the relocating constraint: code production is automated, then verification is solved, then feature selection is solved, leaving what deserves to exist as the frontier

I find this frame everywhere, because it is everywhere. A team’s output is bounded by its weakest coordination path, not by how hard anyone works. A career is bounded by the skill you keep avoiding, not by the one you keep sharpening. A life is bounded by the activity you will not stop doing even though it stopped mattering years ago. The work is always the same: find the layer where the constraint currently lives, push there, and then go find it again. The people who look busy and ineffective are usually pushing somewhere the constraint is not. The people who look calm and effective have simply learned to feel where it is.

Games are one of the places I reach for when I want an analogy, because they externalize the thing I am trying to say. Factorio, StarCraft, World of Warcraft, RollerCoaster Tycoon: each is a simulation with a binding constraint, a compounding resource, and a goal that is easy to forget while you optimize a sub-goal, which is why I wrote a series mapping each onto software. The factory exists to launch the rocket, not the other way around, and every optimization that does not serve the product is a belt to nowhere. Analogies are not how I think all day; they are how I explain, and sometimes how I notice a pattern I had not named yet. A trade-off that sounds abstract in software can become obvious when you see its equivalent in a game: you spent the minerals on the wrong unit, you hit the supply cap, you optimized a belt that leads nowhere.

The axis: compounding versus depreciating
#

If the constraint frame tells me where to push, the compounding axis tells me what is worth pushing on at all. Every activity, skill, fix, and artifact is either compounding or depreciating. Compounding things leave future me more valuable for having done them: foundation knowledge, taste, specifications, encoded standards, durable mental models, relationships with people who grow. Depreciating things melt as the environment moves: boilerplate, syntax, one-off patches, anything the next model release will do for free.

My decision tool is the two-year test: if I let this continue for two more years, does the me that emerges become more or less valuable? This looks like a time-management question, but it is an ethical one in disguise. It encodes a belief that a life is something you invest in, not something you spend.

The discipline is asymmetric, and I state it as a rule: delegate depreciating activities ruthlessly, and protect compounding activities ferociously. Protecting a depreciating activity in the name of craft is not craft; it is nostalgia with a deadline. But delegating a compounding activity in the name of efficiency is not efficiency; it is capability suicide by installments. The number to watch is not how much I delegate; it is how much of my remaining time lands on compounding work.

The method: write everything down
#

I do not trust my brain to hold anything important, because I have watched it drop too many important things. So I externalize compulsively: notes, daily questions, workstacks, process documents, this blog. Anything that lives only in a head dies the moment you switch teams, or get tired, or get interrupted. Writing does not degrade as it passes through people; speech does, so I write decisions down.

Writing also does something the brain cannot: it makes what is implicit explicit, so it can be iterated on instead of left unrecorded. A principle in the head is a feeling that I roughly agree with; a principle on the page is a sentence I can sharpen, test against a counterexample, version, and improve. I treat my own notes and principles the way I treat code: something to refactor when it no longer holds, not something to revere because I wrote it once. An unrecorded thought cannot be revised; it can only be had again, slightly differently, next year.

And, finally, I write because I do not know what I think until I do. The first beneficiary of anything I write is me, because the act of writing is the act of finding out what I believe. A verbal decision is just an opinion that hasn’t been overwritten yet; a written one travels to the rooms I am not in and makes its case without me. This is why the blog exists, why the principles file exists, why the daily questions exist. They are not records of conclusions I had already reached. They are the instrument that reaches them.

Then I encode. If a rule lives only in my review comments, it runs only when I am awake, looking, and willing to argue. If it lives in a gate, a template, a paved path, it runs always. A standard runs whether or not anyone agrees with it. An opinion dies the moment you go on vacation.

Verify, do not trust
#

I am an empiricist by temperament, and I do not trust output; I trust the verification system behind it. A claim without an independent check is a hypothesis, not a result. Its confidence is not evidence. Once a system can produce faster than I can read it, review stops being a useful gate and becomes an empty ritual. The right approach is to push human attention upstream to specification, let machines verify compliance downstream, and operate on reality rather than prediction. A canary, a feature flag, a test that actually runs: these are more reliable than a tired human scanning a diff.

The same skepticism turns inward. I treat my own practices and opinions as hypotheses to test, not identities to defend. When I change my mind I try to do it structurally, not shamefully; the meta-process compounds while the specific answer does not. Consistently wrong is worse than inconsistently right, and the only way to avoid being consistently wrong is to keep asking what would change my mind.

Attention is the one resource I cannot manufacture
#

Attention is the binding constraint of my life, so I treat it as the thing the whole system is designed to protect. Keeping up is a losing strategy; the target moves faster than any consumption can match.

The move is not to consume more but to build a funnel that throws almost everything away, confidently and without guilt. Treat urgency as a sales pitch from someone with an incentive to inflate it. Prefer pull over push: knowing where to find something when I need it beats knowing it now. Re-audit the filter periodically, because filters are themselves depreciating assets.

Asymmetry favors the tighter filter. I would rather miss something than be drowned by it, and I would rather be surprised by a concept I can reuse for a decade than briefed on ten things I will forget next week.

The moral register
#

I keep this part out of most of my writing, because it does not look like the rest, but it is central. My philosophical home is Stoic. The happiness of your life depends upon the quality of your thoughts. People are frugal in guarding their property but wasteful of the one thing in which it is right to be stingy, which is time. He who spares the wicked injures the good. These are not decorative quotes to me; they are the axioms the rest has to be consistent with.

From which: tolerate bad behavior and you harm the good; never discourage anyone who continually makes progress no matter how slow; a fast, clear no is a gift, not an injury; skip the blame during the incident and save it for the post-mortem; a father who can admit in writing where he fell short gives his children permission to be imperfect too. I keep a register of my own failures, not as self-punishment, but because a rule without its wound is a slogan, and the wound is the part that is actually useful to inherit.

I am existentialist about meaning and utilitarian about consequences, and I see no contradiction. Life does not have a meaning. You define the meaning of your life. From there, the reasonable project is to reduce pain or increase capability for the largest population you can reach, accepting that capitalism will mostly reward you for producing work whose purpose is, in the grand scheme, about survival. I do not find this grim; I find it clarifying. It means the meaning is mine to assign and the assignment is allowed to be revised.

Set your own standard
#

Do not define your identity by what the people around you do. If their standards are lower than yours and they do things you do not want to see done, that is not permission to lower yours to match. Most people drift toward the average of their environment without noticing, and the excuse is always that everyone else is doing it. The fact that someone else cuts a corner does not make the corner straight.

Be your own standard setter. Be what you would want others to be, regardless of whether they are. The standard is not a comparison to the people next to you; it is a comparison to the person you decided to be, and who you were before.

In one sentence
#

Encode your judgment into artifacts that outlive your attention, from the skill file to the principles file, because that is the only move that simultaneously finds the bottleneck, compounds the foundation, protects the taste, and lets you become unnecessary at the layer you have finished building.

See also
#

References
#


Whoever Ships First Decides

I looked at a feature a colleague shipped last week, and it was wrong in the ways I would have predicted. Not broken, just built on shortcuts I knew we would pay for later. I had no time to spare, and reopening the decision would have taken a meeting, a design argument, and most of a sprint. So I said nothing, and his version became the version the team now supports.

This is how the standard on a team actually gets set: not by what anyone agrees is correct, but by what someone was willing to ship before the rest of us could object.

The interesting question is not whether the work was bad. The interesting question is why bad work, once shipped, almost never gets undone, even when everyone quietly knows it is bad.

“Done” Changes the Question
#

Before the work exists, the question on the table is “is this the right approach?” Once it ships, the question quietly becomes “is it worth fighting to change this?” Those are different questions, and the second one is almost always answered no.

The reason is not that the work got better when it merged. It is that reversing it now costs something it did not cost before. You have to schedule a conversation, justify the rework to someone who already feels they finished, and spend a credibility budget you were saving for your own work. Letting it stand costs nothing in the hour you notice it. So you let it stand, and so does everyone else who noticed.

A piece of work does not have to be good to survive. It only has to be done, because done work turns a technical judgment into a political cost, and political costs are paid by the person who raises them.

The Cost to Object Is Concentrated. The Cost to Absorb Is Hidden.
#

The whole pattern rests on this one asymmetry.

Objecting to bad work is expensive in the moment, and you pay the full bill yourself. It is your afternoon, your difficult conversation, your reputation as the person who slows things down. The benefit of objecting, if you win, is spread across the team and across the next year, and most of it lands on people who will never know you fought the fight.

Absorbing the bad work is the opposite. It is free in the moment, and its cost is distributed across the whole team and deferred into the future, where it shows up as the friction of working around a decision nobody loved.

Faced with a cost that is large, immediate, and personal, against a cost that is small, deferred, and shared, almost everyone picks the second one. That is not laziness. It is a rational response to badly priced incentives.

The bad call survives not because anyone thinks it is good, but because the person who would have objected was busy, and objecting then would have cost them their afternoon, and they did not have an afternoon.

The Bar Drifts to the Most Willing Shipper
#

Once you accept that done work is sticky and objection is expensive, a consequence follows that most teams never state out loud.

The effective quality bar is not set by what the team agrees is correct. It is set by whoever has the lowest bar and the highest willingness to act first.

If you ship before anyone can object, your version becomes the default, and the default is what everyone else now has to spend energy to dislodge. The person who cares about doing it right is at a structural disadvantage. Doing it right takes longer than doing it fast, and by the time the careful version is ready, the fast version is already the reality.

The disadvantage compounds. Other people copy the shortcut, because the shortcut is now the pattern the codebase rewards. The exception becomes the convention. A year later, nobody remembers that the pattern started as a shortcut someone shipped under deadline. Defending the shortcut has become the team’s default position, because that is what defaults do.

The drift compounds in one direction:

One-way timeline from a shortcut shipped under deadline to it becoming the default, being copied, becoming the convention, and being defended by default

Teams do not converge on their best engineer’s standard. They converge on whatever the most active shipper leaves behind, and they call it the way things are done here.

The Cost Was Never Avoided. It Was Moved.
#

Every time a team absorbs bad work, it tells itself the absorption was free. It was not.

The cost was simply transferred, from one person’s afternoon of objection to the whole team’s months of working around the decision, and from a bill addressed to the moment into a bill addressed to the future.

Then the rework arrives, and it is always larger than the objection would have been. By the time the shortcut finally breaks badly enough to force a rewrite, other code has been built on top of it, the original author has moved on, and the team is paying to redo work it already paid to do once.

This is the cruel accounting of absorption. It looked like the cheap option only because the cost arrived later and was borne by someone else. The full cost, plus interest, lands on whoever still works near the code when it finally fails.

The Decision Was Usually Unsound for a Reason
#

It is worth noticing why the shipped work is so often the wrong call, because it is rarely because the author was incompetent.

The person who ships first is usually optimizing for the thing in front of them, getting something working, hitting a deadline, unblocking a demo. The costs they are creating live somewhere they cannot see: in the downstream maintenance, in the constraints they did not know about, in the parts of the system their shortcut quietly contradicts.

They made a locally reasonable decision that is globally wrong. Nobody was in the room to add the global view, because the work was already done by the time the people who held that view heard about it.

The person closest to the keyboard is rarely the person closest to the consequences, and shipping first lets them decide for everyone without ever holding the cost.

The pattern is not only a problem with AI-generated code, though cheap generation has made it worse. It is the older and more general problem of whoever acts first setting the default for everyone who acts later, and it applies just as cleanly to a human’s rushed pull request as to a model’s confident output.

What to Do Next
#

You cannot make objection free. You can make it cheap enough that it happens before the bad work hardens into the default, and that is where the leverage is.

Object in writing the moment you see it, even if you cannot fix it now. A single line saying “this shortcut will cost us in X” takes two minutes, costs almost no political capital, and does two things at once. It puts the author on notice that the decision was not unanimous, and it leaves a record so that when the cost arrives later, the pattern is traceable instead of invisible. The absence of objection is not consent. It is a measure of how busy everyone was, and writing it down stops that absence from being read as agreement.

Price the absorption out loud. When you absorb bad work to keep moving, say so, and say who will pay: “I am taking this as-is to hit the date, and we will redo it next quarter, and that rewrite is the cost of shipping it now.” Naming the tax prevents the team from pretending the absorption was free, which is the fiction that lets the pattern repeat.

Lower the cost of the conversation. A ten-minute “I would build this differently, here is why” is cheaper than a rework, and cheaper than the resentment that builds when you say nothing for six months. Most engineers respond well to a specific, early objection, and badly to a vague, late one, so timing matters more than wording.

Make the shipper own the consequences for a window. The person who shipped the shortcut remains responsible for the bugs it produces, instead of routing them to whoever happens to be nearby. This does not require blame; it just re-attaches the cost of the decision to the person who captured the benefit of shipping it, which is the alignment the current default removes.

And if you are the one who shipped, treat silence as the weak signal it is. “Nobody objected” does not mean everyone agreed. It means everyone was busy, and the most accurate reading of a quiet merge is that you got away with it, not that you were right.

The standard on a team is set by what survives, and what survives is whatever was too expensive to undo. If you want a higher standard, do not ask people to object harder. Make objection cheap, make absorption visible, and make the cost of shipping bad work land on the person who shipped it, and the bar stops drifting on its own.

See also
#

References
#


Distributed Product Management: Cheap to Decide, Costly to Undo

Distributed product management is what happens when there is no dedicated product owner, and the people building the product also decide what the product should be. Each engineer, or each small team, makes product calls inside their own area, and those calls aggregate into the product without anyone coordinating the whole. The arrangement removes a real bottleneck, the single product manager, and it removes something less obvious at the same time: the friction that used to force independent decisions to agree with each other. In the age of LLMs that friction is already gone, which is why a structure that used to be merely risky has become quietly destructive.

What Distributed Product Management Actually Is
#

The dedicated product owner is a specific role: one person who holds the product’s direction, decides what gets built and what does not, and is accountable when the result is incoherent. Distributed product management dissolves that role and spreads its responsibilities across the engineers doing the work.

It shows up in a few familiar forms. Small teams that never hired a product manager and let the founders or lead engineer set direction. Open-source projects, where maintainers decide what to accept and what to build, with no owner above them. “Empowered teams,” in the sense Marty Cagan describes, where a cross-functional team is given a problem to solve rather than a feature to implement, and the team decides the solution itself. And, increasingly, engineering cultures where LLM-assisted development has made shipping so cheap that waiting on a product decision feels slower than just making one.

In all of these, the same property holds. The person deciding what to build is the person building it, and there is nobody whose job is to keep the pieces coherent.

The Case For It
#

The merits are real, and I do not want to understate them, because they explain why the arrangement is so common.

It removes a genuine bottleneck. A single product manager is a single point of coordination. When they are slow, blocked, or absent, the whole team waits. When there is no owner in the path, decisions move at the speed of engineering.

Decisions sit with the people closest to the problem. The engineer implementing the feature usually has more context about the technical reality and the user’s actual behavior than a product owner who learned the domain second-hand. Moving the decision to where the context already lives avoids a translation step, and it avoids the gap between a spec and what the spec was supposed to mean.

Ownership produces motivation. People who decide what they work on care about the work in a way that people handed a task do not, a cost I have felt directly in finishing work I did not choose. Distributed product management lets engineers keep that investment.

It scales without growing an organization. A dedicated product owner has a finite span of attention. As a product grows, either the owner becomes a bottleneck or you have to hire and coordinate more of them. Distributed product management scales with the number of engineers by default.

Each of these is a good argument. Together they explain why the structure keeps reappearing, and why it often works well for a while.

The Case Against It
#

The problems are also real, and they take longer to show up, which is why they are consistently underestimated.

The product loses coherence. A product is a system of decisions that have to agree with each other. When each decision is made locally and optimally, the result is a local optimum: every piece is reasonable on its own, and the whole is worse than any of its parts. Two engineers build two ways of doing the same thing. A new feature uses a pattern that contradicts the one shipped last quarter. The surface area grows, and nothing ties it together.

Nobody owns the whole. Coherence is not a side effect of good local decisions. It is a separate concern, the job of noticing the global pattern and sacrificing a local win when it would break that pattern. Without an owner, that job has no home, which means it does not get done. This is the tragedy of the commons applied to a product: the shared surface that everyone uses and nobody maintains.

Nobody is paid to say no. The hardest part of product work is deciding what not to build. A dedicated owner can kill a feature because they are accountable for focus. An engineer building in their own area has no incentive to decline their own idea, and no authority to decline anyone else’s. The result is feature accumulation, the same failure mode that turns a backlog into a dumping ground, except it ships directly into the product.

Cross-cutting decisions have no owner. Some decisions only make sense globally: the pricing model, the data model, the API conventions, the identity of the product. These decisions occasionally require one team to accept a worse local outcome so the whole can stay consistent. Distributed product management has no mechanism for that trade, because no one is authorized to impose a cost on one part to benefit another.

The strategy drifts, silently. When every team optimizes for the metric in front of it, the product as a whole drifts toward whatever those local metrics reward, and that direction is rarely the one the company would have chosen deliberately. This is Goodhart’s law at the level of the product roadmap: each local signal looks reasonable, and the aggregate stops pointing anywhere worth going.

The common thread is that distributed product management is excellent at producing decisions and bad at producing a coherent product. For a long time, that trade was manageable, because the cost of building kept the decision rate low.

Why LLMs Make the Trade Worse
#

Here is the part that has changed.

The friction that used to keep distributed product management tolerable was the cost of implementation. Building a feature took days or weeks, and that cost forced a conversation before the work started. An engineer who wanted to ship something had to justify the time, coordinate with the people whose work it touched, and get the change reviewed. The friction was accidental, but it was doing useful work: it throttled the rate at which independent decisions could accumulate.

LLMs have removed that friction. An engineer who wants to ship a feature can now spec it, generate it, and open a pull request in an afternoon, without asking anyone whether the feature should exist. The cost of making a product decision and the cost of the decision’s consequence have been decoupled. The first one collapsed toward zero. The second one did not.

This is what makes distributed product management destructive in the current era rather than merely inefficient. When decisions were expensive, an incoherent product was a slow problem that you could notice and correct. When decisions are nearly free, the incoherence arrives faster than any human can track it, and the cost shows up downstream: in a codebase nobody wants to touch, in a feature surface nobody can fully use, in the slow accumulation of a house of cards built from locally reasonable additions.

The deeper problem is that cheap decisions change who decides. When a product decision required a meeting, the decision belonged to whoever ran the meeting. When it requires only a prompt, the decision belongs to whoever types first. That is a change in governance that looks like a change in speed, and most teams have not noticed it happened.

It is worth saying what this argument is not claiming. It is not claiming that engineers are bad at product judgment. Many are excellent at it, and the bottleneck has moved toward exactly that judgment as implementation has been automated. It is claiming that good individual judgment, applied independently and at machine speed, with no coherence layer above it, produces a worse product than the same judgment applied inside a shared frame.

The Real Question Is Which Decisions to Distribute
#

The way out is not to bring back the single product manager as a gatekeeper. That would reintroduce the bottleneck distributed product management was right to remove. The way out is to notice that “product decisions” is not one category, and that the right structure differs by decision type.

A useful split comes from the one-way door versus two-way door distinction. Some decisions are reversible. If you ship the wrong notification wording, or pick the suboptimal layout for a single screen, you can change it next week with low cost. These decisions should be distributed, because distributing them removes friction without risking much.

Other decisions are effectively irreversible. What the product is, which problem it solves, which abstractions it commits to, how the pieces fit together, these set the trajectory of everything built on top of them. Once a thousand features depend on a data model, the model is no longer negotiable. These decisions need a single owner, not because the owner is smarter but because coherence requires that someone be able to choose the global over the local.

The split is a routing rule, and it is easiest to apply as a decision:

flowchart TD
    D[A product decision] --> Q{Is it reversible}
    Q -->|yes, a two-way door| R[Distribute it to the team closest to the context]
    Q -->|no, a one-way door| O[Single decision-maker plus a written record]
    O --> G[Someone can choose the global over the local]

The failure mode of distributed product management is not that it distributes decisions. It is that it distributes the irreversible ones along with the reversible ones. Most teams that suffer from “no product owner” are actually suffering from no owner for the small set of trajectory-setting decisions, while the reversible ones are handled fine. Diagnosing which set is causing the pain is more useful than arguing about whether to have a product manager at all.

What to Do Next
#

If your team operates without a dedicated product owner and the product is starting to feel like a patchwork, a few concrete moves help.

Write the product direction down, in one place, and keep it current. This is the single highest-leverage action, and it is the same lesson as breaking the scope relitigation cycle: a direction that lives in heads cannot survive contact with the next person or the next quarter. A short, written north star, the milestones you are committing to now, and the constraints that forced the compromise, give distributed decisions something to check themselves against. Without it, every engineer is optimizing for a slightly different product that exists only in their head.

Separate the two questions explicitly. On every non-trivial decision, ask first whether it is reversible or trajectory-setting. Distribute the first. Force the second through a single decision-maker and a written record, even if that decision-maker is a rotating engineer rather than a hired product manager. The role matters less than the fact that someone owns it.

Encode product-level invariants the way you encode engineering conventions. The teams that keep coherence without a full-time owner are the ones that have externalized their standards into a form the work has to satisfy: style guides for the product surface, principles for which features are in scope, a definition of what the product is not. This is the same mechanism that lets a mature team scale its conventions into the model. A convention in a head is advice that gets ignored. A convention in a written principle is a constraint that gets enforced.

Keep a thin, intent-level review for product decisions, as a backstop and not a bottleneck. The point is not to gate every change. The point is to catch the small fraction of changes that are individually reasonable and collectively incoherent, the second implementation of an existing feature, the new pattern that contradicts the established one, the locally optimal choice that breaks a global invariant. This is the product equivalent of the intent check I keep on LLM-generated code: light by default, held back for the changes that carry real risk.

Reallocate the time you saved on implementation into judgment. The instinct, once implementation is cheap, is to ship more. The correct response is to decide more carefully, because the cost of being wrong has not come down even though the cost of acting has. Time spent on problem selection and direction now buys more than time spent on execution ever did.

The Dedicated Owner’s Real Job Was Coherence
#

Distributed product management is not wrong. It removes a real bottleneck, it puts decisions close to the context, and it scales without growing an organization. The mistake is concluding that because the dedicated owner was unnecessary, the thing the owner was doing is also unnecessary.

It was not. The owner’s real job was coherence: holding the whole product in one head, killing the features that did not fit, and choosing the global over the local when the two disagreed. Remove the person and you still have to keep the function, or accept that the product will be built faster than anyone can keep it coherent.

In an era when a product decision costs an afternoon and its consequences last for years, the scarce resource is no longer the ability to decide. It is the ability to decide in a way that still makes sense next to every other decision the team is making at the same time. That is the bottleneck distributed product management has to solve, and LLMs have made it urgent rather than theoretical.

See also
#

References
#


What I've built and what I need: July 2026

The headline this month was llm-augmented-workflows carrying an issue all the way through to a human gate. Underneath the headline, the month spread into maturing the SDLC pipeline, reworking PR validation around visual proof, and shipping a wave of new skills.

What I Have Been Working On
#

Iterating on llm-augmented-workflows. The project is still rough, but it now moves an issue through real stages instead of demoing a single one. A cycle looks like this: an issue is created, it gets triaged, and the appropriate workflow runs until it hits a stage that requires a human. For feature requests, the workflow runs triage into a plan PR for review, and once the plan merges, continues to an implementation PR. For bug fixes, the flow goes from triage into a fix PR rather than stopping at reproduction. Triage is handled end to end, which closes a point I’d written about in earlier posts. I’m building it to support both human-gated and fully autonomous modes from the start, so the same flow can run with or without checkpoints.

The cycle is easiest to follow as a flow:

flowchart TD
    I[Issue created] --> T[Triage]
    T -->|feature request| P[Plan PR]
    P --> R[Human review]
    R -->|plan merges| IMP[Implementation PR]
    T -->|bug fix| F[Fix PR]

Building github-board. github-board is a frontend-only web application, served directly via GitHub Pages, that lets you build columns and rows from any field on a GitHub issue or pull request. It turns issue and PR data into a configurable board view with no backend.

Adding the resolve-pr-conflicts skill. I now run the skill daily across the repositories I contribute to. It scans for my open pull requests that have merge conflicts and resolves each one in parallel, fanning out a separate agent session per PR into its own worktree. Each session merges the base branch, resolves the conflict markers, runs the project’s verification, and pushes, while ambiguous or verify-failing resolutions get aborted rather than guessed. The practical effect is that my PRs stay mergeable without me babysitting rebase loops.

Refactored the SDLC pipeline. Feature directories dropped the FEAT-NNNN- prefix for N-<slug>, and pending items now carry a p prefix with a promotion flow through create-placeholder-issue. The old questions.md drift log is gone, replaced by a review-verdict regression that sync-sdlc and backpropagate-sdlc track across phases. Review findings now persist to files instead of disappearing, and I slimmed the create-* family by roughly 750 lines by pointing each at templates and giving it a self-check checklist. Each phase skill is now explicitly loaded before it runs, and a needs-assessment template joined the pipeline.

Reworked PR validation around visual proof. Visual proof capture moved out of create-pr into a dedicated validate-implementation skill, which writes a proof manifest before the PR is ever opened, so recording happens before creation rather than during it. Bug fixes now capture before/after recordings via reproduce-issue and fix-issue. And validate-pr and verify-pr now check against the issue’s acceptance criteria rather than the PR’s own claims, with body and footer split for GitHub attribution.

Shipped a wave of new skills. Slack and memory support landed with slackx and sessions-memory, which turns archived sessions into PARA memory. Team docs gained create-team-api and create-team-charter. Codebase upkeep got improve-codebase, improve-skill, sync-documentation, and sync-opinions. Planning expanded with create-goals, create-service-levels and their review-* counterparts, create-mockups, and create-placeholder-issue. Issue triage gained check-issue-status, check-issues-status, and check-linked-pr. Demo tooling arrived with research-topic, record-asciinema, and record-playwright.

Tidied conventions. gh-cached was replaced by ghx and removed, with every skill reference switched over. The dot-claude directory was renamed to agents. The AGENTS.md vocabulary now avoids “shape”, “honest”, and “load bearing”. SDLC status pages went mobile-friendly.

Experimenting with article-to-video. I started generating short videos from the articles I write, to post on YouTube and TikTok. The pipeline combines text-to-speech narration with visuals that follow the article’s content. The experiment is early, but it’s a plausible way to reach a wider audience with the ideas I’ve been working through.

Resolved from last month. Scheduled issue-to-PR automation (#8) and automatic context clearing between execution and review (#9) both landed through llm-augmented-workflows. The automation was generalized beyond OpenChamber, and the context clearing came free because each phase runs in its own session. Skill usage tracking (#7) is handled after I extended agentsview to collect skill-usage statistics from its SQLite database. Because the data is queryable, an agent can search session logs for skill calls and extract which skill ran, and the same approach works across every harness agentsview supports. Reliable bug reproduction comments (#10) are handled by llm-augmented-workflows, which can enforce an expected outcome and, when the agent doesn’t deliver it, resume the last session and ask again. The llm-augmented-workflows flexibility rework is done. I’ve also fully switched to opencode, though support for other harnesses isn’t there yet.

Partial progress. The SDLC status report got significant improvements, but a status script in TomzxCode/sdlc now duplicates the report and drifts out of sync with the agents-repo skill. Loops only run at the start and end of day, week, and month so far. The easiest remaining task I have not picked up is auto-running validate-pr, verify-pr, and review-pr on PRs waiting on me. And validation of other people’s changes is now covered by validate-pr and verify-pr, but for my own changes I still default to manual testing instead of delegating to an agent.

What I Currently Need
#

Five needs from earlier months are still open.

Clarity on verdict propagation. I need to confirm how a verdict (approve, reject, needs-changes) made at one stage propagates to downstream stages. Until I can trust that the right decision always carries forward, I can’t confidently run the autonomous path without a human checking each handoff.

A full pass on flow definitions. The flow definitions still have issues I haven’t fully mapped. I need a round of end-to-end testing to find where the definitions diverge from intended behavior, so the defects get fixed rather than worked around.

A faster path to implementation. For feature work, I need to figure out which SDLC steps can be safely skipped or compressed to reach implementation faster. The full chain is thorough but slow, and it’s still unclear which steps are essential and which are ceremonial.

State tracking for an orchestrator-only llm-augmented-workflows. Resolving the context-clearing need surfaced a bigger question: the engine could run as its own orchestrator instead of always anchoring on a GitHub issue. The blocker is that without an issue to hold state, the engine needs another way to track where a run is, and I haven’t decided what that state store should be.

A set of PDLC skills, mirroring the SDLC ones. At work I’m spending a meaningful share of my time on product management work, and I want the same repeatability there that the SDLC skills give to engineering. I need a structured set of product development lifecycle skills for discovery, framing, prioritization, and measurement, so the product side gets done properly and the same way every time rather than ad hoc.

See also
#

References
#

  • llm-augmented-workflows - the engine driving the issue-to-PR pipeline described throughout.
  • agents - the skill library where the SDLC refactor, validation rework, and new skills landed.
  • agentsview - the session archive extended to track skill usage across harnesses.
  • TomzxCode/sdlc - the static SDLC status pages, whose report script now overlaps the agents-repo skill.
  • github-board - the frontend-only issue and PR board view shipped this month.
  • ghx - the GitHub CLI that replaced gh-cached across the skill library.

The Cost of Work You Did Not Choose

A colleague handed me a task last week. The job was to take their work, get it running, and get it merged. I did not volunteer for it, and nobody asked whether I wanted it. It took me almost three days.

I want to be careful here, because the easy reading of this story is a complaint about a colleague, and that is not the interesting part. The interesting part is why a piece of work that should have taken hours stretched into days, and what that says about how work gets assigned. Work you did not choose takes longer, not because it is harder, but because nothing pulls you through it.

The Task Was Not Hard. The Task Was Not Mine.
#

The work itself was not especially complex. What made it slow was that I had no investment in it. I had not chosen the problem, I had not designed the solution, and I stood to gain nothing from its completion except the relief of being done with it.

There is a motivation tax on work you did not choose, and it is larger than most people account for. When a task is yours, the friction of a confusing codebase or a failing test is a puzzle you want to solve. When a task has been dropped on you, that same friction is an obstacle between you and being somewhere else, and every obstacle feels twice as tall.

The three days were not a measure of the task’s difficulty. They were a measure of the distance between me and any reason to care.

Finishing Someone Else’s Work Is Not Half the Job
#

There is a common assumption that handing off nearly-finished work is cheap, because the hard part is done. This is almost always wrong. Code that someone else wrote carries their hidden decisions: names that made sense to them, assumptions they never wrote down, edge cases they handled in their head and nowhere else.

To get another person’s work to a mergeable state, you have to reconstruct the intent of a person whose reasoning you never saw. You become an archaeologist of their intent, reading commits like strata. And unlike your own code, where you remember why you wrote each line, here every unfamiliar line is a small investigation.

“Get this merged” sounds like a small favor. It is a request to absorb someone else’s unfinished thinking, under a deadline you did not set, for a result you will not own.

Distractions Stick When There Is No Pull
#

I noticed something during those three days that I would have missed if I had been excited about the work. Distractions did not just interrupt me. They rescued me.

When you are working on something you care about, a notification is an annoyance you dismiss. When you are working on something you resent, a notification is a permission slip to step away, and you take it every time. The work expanded to fill three days in part because every ping, every message, every side question offered a more appealing place to put my attention, and nothing pulled me back.

The same afternoon forks in two depending only on who chose the work:

Attention chart: chosen work holds a flat high line while assigned work decays in a sawtooth at every notification

Distractions are not the enemy of focus. They are the enemy of focus on work you do not want to do. On work you want to do, focus defends itself.

The Real Failure Was the Hand-off
#

The colleague is not the villain of this story. What failed was the assumption that a task could be moved from one person to another by declaration, without a conversation about whether it should be.

When you assign work without asking, you are gambling that the person receiving it has the context, the capacity, and the motivation to carry it. You have checked none of those things. You have simply moved an item on a board and assumed the work would move with it.

The cost of that gamble does not show up on the board. It shows up in the three days, in the half-attention, in the quiet resentment that makes the next hand-off harder to accept. A task assigned without consent arrives already taxed, and the tax is paid in time.

What I Will Do Differently
#

I am not going to pretend the lesson is that I should have said no. In a team, sometimes you absorb work that is not yours, and that is part of the job. The lesson is narrower and more useful.

When work arrives by declaration rather than by agreement, I will name the motivation cost out loud, early. I will ask for the context I am missing instead of reconstructing it silently. And I will be candid, with myself and with the person handing it off, about what “get this merged” actually entails, because the favor is rarely as small as it sounds from the side that is handing it off.

Work you did not choose takes longer, not because it is harder, but because nothing pulls you through it. The friction was not in the task. It was in the absence of a reason to care.

See also
#

  • Task overload - the moment you have more on your plate than you can handle, and how to re-prioritize from scratch
  • task-stack - a tool for managing the interruptions and context switches that compound when you have no intrinsic drive to push through