Agentic: a work tracker for coding agents
Most of my work now starts with an agent, and most of the time goes to telling the agent what the work is.
The issue sits in one tab, the Slack thread in another, the checkout in a third, and the last session’s conclusions exist only in that session’s transcript.
The slow part of delegation is not the agent writing code, it is rebuilding the context around the work each time I return to it.
Agentic is the tool I built to remove that cost: a local-first work tracker where a task holds its sources, its checkout, its agent runs, and a summary the agent refreshes on demand.
The agent does not remember the work for you #
A coding agent is fast inside one session and starts the next one without the work’s context. It can read a repository, run the tests, and produce a patch in minutes. It cannot tell you why the task exists, who is waiting on it, what was already tried, or which of the five open branches is the one that matters.
That context lives in the systems around the agent, and for a single developer those systems are held together by memory. I kept writing one-off tools to fetch an issue, to open a worktree, and to remind myself what a branch was for. Each tool solved its problem and then sat unused, because the cost of remembering to run it was higher than the cost of re-reading the source. Agentic is the consolidation of those tools into one record that all of them feed.
A task is the unit, and everything attaches to it #
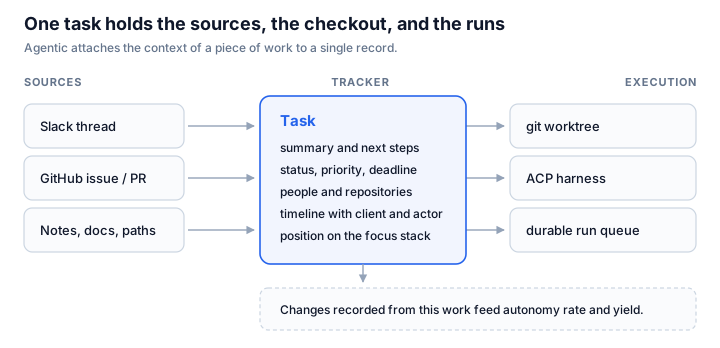
Agentic starts from one record, the task. A task carries a description, a status, a priority, tags, a deadline, and a timeline of every meaningful change made to it. Everything else attaches to that record.
- Items are the external sources of the work: a Slack thread, a GitHub issue or pull request, a Drive document, a URL, a note, a commit, or a local file or directory path.
- People are the people involved, kept in a directory and linked to tasks and items. A fetched GitHub issue brings its author, assignees, and commenters, and a Slack thread brings its participants.
- Repositories are registered checkouts. A task can span several, and a repository group tells the agent which checkouts may hold information about it.
- Worktrees are isolated
git worktrees created for one task from one repository.
- Runs and sessions connect the task to an agent.
A run is one prompt sent in a working directory, and a session is the agent session recorded against the task, with links to reopen it in a terminal or in
OpenChamber, a session UI for OpenCode. A session you started elsewhere can also be attached to a task by hand.
The reason to keep all of them on one record is that each one is context I would otherwise rebuild before starting work.
Pasting a URL is enough to create an item, because the app infers the source from the link.
GitHub items are read through ghx and Slack threads through
slackx, two local tools I built for the same workflow.
A path stays a reference to the file on disk, read live when opened and never copied into the database.
The payoff is that resuming a task costs a read. You open one page and see the issue, the discussion, the people, the branch, what the agent concluded, and what you decided to do next.
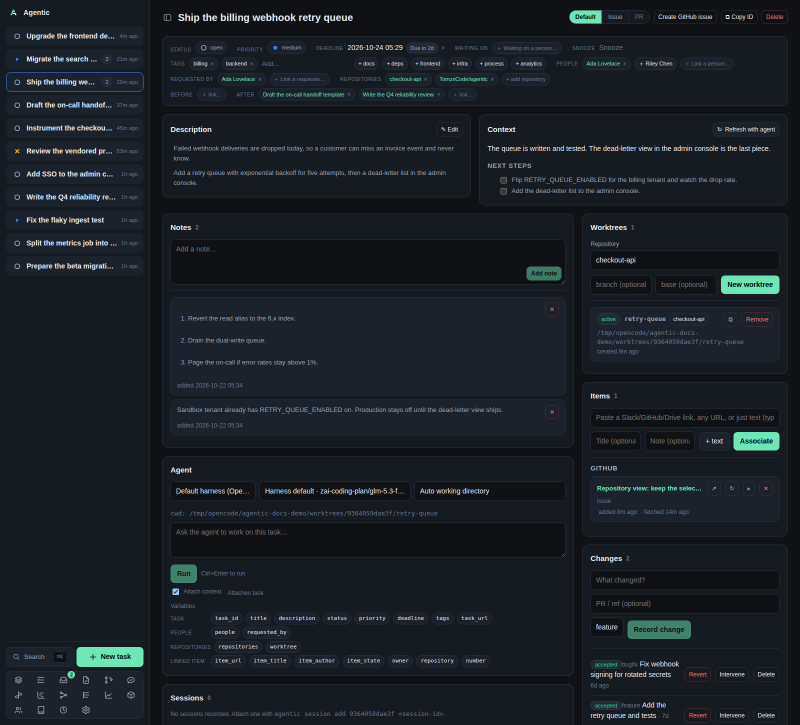
The app also keeps a focus stack, an ordered queue of the work in flight with the current task on top. Every open, in progress, or blocked task joins the stack automatically, so the queue never needs manual maintenance. A task that waits on a person, or is snoozed until a date, leaves the stack and returns when the date passes.
The agent maintains its own context #
The feature that changed how I use the tool is Refresh with agent. It runs an agent against the task and its linked items and asks it to write two fields: a summary of where the work stands and a list of next steps. Those fields live on the task, not in a transcript, so the next session starts from a prepared summary instead of a blank prompt.
That only works because the agent can read and write the tracker.
The agentic CLI is a client for the same HTTP API the web app uses, with JSON output by default when piped.
It covers tasks, items, worktrees, runs, and sessions, so an agent can create a task from an issue, link a source, move a status, read the stack, or stream a run without a browser.
agentic task create --github-url https://github.com/owner/repository/issues/42
agentic run create <task> --prompt "Investigate the failure"
agentic run stream <run-id>
The CLI and API also record provenance. Every timeline event carries the client it came from (web, CLI, or API) and whether a person or an agent did it, and every mutating request lands in an operations log. When a task changes at 3 a.m., the record says whether a person or an agent changed it and through which interface.
Any harness, one durable queue #
Agentic does not embed an agent.
It speaks the Agent Client Protocol over stdio, so each harness is a command in a database table rather than code in the app.
OpenCode and pi are seeded on first start, and another ACP-speaking harness can be added in Settings.
A run is a job on a SAQ queue backed by SQLite.
The API only enqueues, and a separate worker process dequeues, spawns the harness in the task’s worktree, and streams normalized events back over server-sent events (SSE).
Separating the API from the worker matters in practice.
A long agent turn survives an API restart, a failed run can be retried, and workers scale independently of the web server.
You pick the harness and the model in the run panel, and the choice applies to that run only. A task can keep its default harness and answer a single question with a different model.
Measure how much the agents did alone #
Delegation is only useful if you know what came back without you. Agentic records a change against a task: a class, a status (proposed, verified, accepted, rejected, or reverted), a start and end time, and whether a person intervened.
From those records the Metrics page computes two numbers:
- Autonomy rate is the share of accepted changes that had no human intervention.
- Yield is the share of accepted changes that survived their observation window (14 days by default) without a revert.
You record interventions by hand, so the autonomy rate depends on remembering to record them.
Both are shown against a stored baseline, so the question changes from “did the agent help today” to “is the share of work it finishes alone improving”. Recording is automatic for the common case: when the app sees one of your pull requests merge and a task links that pull request, it records an accepted change.
I wrote about why I want these numbers in Metrics for a Software Factory: Optimize Autonomy, Guard the Trust. A number you can watch weekly is easier to improve than a feeling about how the week went.
Local-first, with the cost stated #
Agentic runs on your machine.
The database is SQLite under ~/.agentic by default, worktrees are created under a configurable worktree root (~/.agentic/worktrees by default), and there is no server to sign up for.
Running locally removes a lot of work.
There are no OAuth flows, no continuous two-way sync, no tenancy model, and no network round trip to read your own task list.
The cost is explicit. There is no authentication and no multi-user isolation, so anyone who can reach the port can read and change everything and start agent runs. Run it on a trusted network, or over a private VPN such as Tailscale. It is also not a team tool: there are no shared workspaces, no permissions, and no hosted deployment.
What it is not #
Agentic is not a replacement for GitHub, CI, or code review. It does not host repositories, run your test suite, or merge pull requests. It is not a cloud agent dashboard. The harness still runs the agent and the code still lives in the worktree, and Agentic is the place where the work is described, tracked, and measured.
It is also early. The project is under active development, the schema migrates in place, and the single-user design is a choice, not a missing feature. If you need a hosted, multi-user tracker, this is the wrong tool.
Try it #
Prerequisites are Python 3.12 or newer, uv, Node 22.12 or newer, pnpm, and at least one ACP harness on your
PATH.
git clone https://github.com/TomzxCode/agentic.git
cd agentic
make install
make run
Open http://localhost:5173, register a repository in Settings, create a task from an issue, press Refresh with agent, then run an agent against it.
That loop is the product: one task, one worktree, one run, and a summary that is current the next time you open it.
If you delegate work across several repositories, track that work where the agent can read and write it, not only where you can.
The documentation starts at tomzxcode.github.io/agentic, and the source is at
TomzxCode/agentic.
See also #
- Coordinating Multiple Agents: From Messages to a Shared Work Ledger - the shared work ledger idea that Agentic’s task record implements for one developer.
- ghx - A CLI for agentic code reviews on GitHub - the GitHub client Agentic reads issues and pull requests through.
- What I’ve built and what I need: October 2026 - the monthly update where consolidating one-off tools into Agentic is the headline.
- Global Sessions: A Git Model for LLM Agent Context - the problem of carrying agent context between sessions.
References #
Agentic documentation - the tutorial, how-to guides, view pages, reference, and explanations this article draws on.
Agent Client Protocol - the protocol that lets Agentic drive any harness without app changes.
uv - the workspace and package manager the project installs with.


